
Observations from World Summit AI 2026 and what they mean for 2027
Key takeaways
- The question has changed. In 2025, the question was what AI agents can do. In 2026, it was whether organizations can depend on them once the demo is over.
- Governance has moved inside the workflow. What an agent may access, what it may do, and who takes over when it stops are now design decisions, not policy documents.
- Reliability is engineered, not bought. Recovery after failure, memory that can be corrected, and evaluation of the full path an agent takes matter as much as the model itself.
- Sovereignty means the ability to operate. Compute, energy, skills, and the freedom to switch suppliers decide whether an AI service survives beyond its pilot.
- Value is measured across the whole task. A fast answer that needs extensive checking saves nothing. The people doing the work need a say in where AI assists them.
- Expertise needs protecting. As AI absorbs routine work, organizations must keep the paths through which newer staff develop judgment.
A larger Finnish presence in Amsterdam
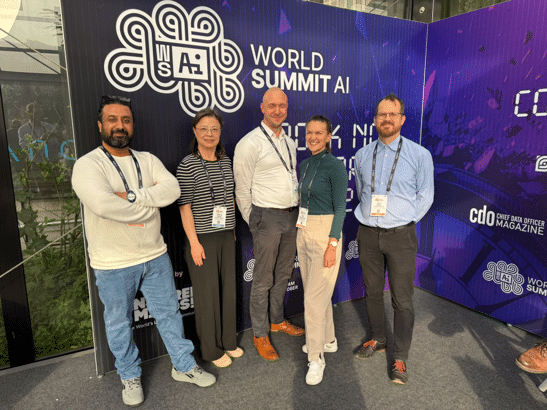
World Summit AI celebrated its tenth edition this October, filling Taets Art & Event Park in Amsterdam on 7 and 8 October with researchers, founders, policymakers, investors, and enterprise leaders. Finland arrived in larger numbers than the year before. Business Finland, Tampere AI, and several Finnish companies travelled together, alongside five participants from GPT-Lab at Tampere University.

A delegation with mixed backgrounds experiences the same event in different ways. Researchers notice open problems. Companies notice tools, partners, and competitors. Funding organizations notice where Europe stands. That diversity is an asset. A question that interests a researcher often matches a problem a company already needs solved, and the most valuable outcome of a trip like this is finding those matches and turning them into joint work.
From "Can it?" to "Can we rely on it?"
The reflection from World Summit AI 2025 described AI taking a practical turn. Agent platforms were moving AI from generating answers to taking part in business workflows, and the energy in the halls was about possibility.
This year the tone was different. The capability itself is no longer in doubt. On the mainstage, in the specialist tracks, and in the hands-on workshops, attention kept returning to what surrounds the model: who controls it, how it recovers when something breaks, what it costs to keep running, and whether it actually improves anyone's work. The workshops turned those concerns into concrete engineering and business problems, such as resuming a task after a crash or deciding whether a pilot deserves further investment.
The common thread is easy to state. The usefulness of AI now depends less on the model and more on the work around it. A capable agent needs a defined place in a process that people understand, support that the organization can sustain, and a real benefit for the person using it. AI has grown up. The open question is whether the practices around it have grown up too.
The observations below are grouped into four connected perspectives. Each asks a different question of the same goal: AI that can be depended on in everyday work.

1. Governance and process: responsibility that reaches the person affected
Governance discussions ran on two levels. At the societal level, the focus was on power: who shapes AI, who can challenge its use, and what consent means when intelligence is embedded in everyday services. Inside organizations, the conversation was far more operational: which information an agent may draw on, which actions it may take, and how those limits are enforced across many tools and teams.
The two levels are connected. Introducing an agent is an act of delegation. The decision affects the employee who uses the system, but it can also affect a customer who never chose to interact with it. Responsibility therefore has to follow the action all the way to the person affected.
Access is not permission. An agent may be able to read a document without being allowed to use it for a particular customer. A technically correct answer can still cross a boundary the organization is obliged to protect. Consider an agent helping a support engineer answer a technical query. Pulling together knowledge from across the company could save hours, provided the system respects the conditions under which each piece of that knowledge may be shared. Governing context, meaning information judged in relation to the task and the recipient, is where governance becomes practical.
Handover is a design task. Much of what keeps work moving depends on tacit knowledge: an employee spots an exception and knows whom to ask. When an agent takes over part of that work, the moment of escalation has to be designed deliberately. The person stepping in should receive enough context to continue without reconstructing the task from scratch.
Agent sprawl is the next governance problem. Teams across a large organization can each deploy useful agents, and within months nobody has a full picture of what those agents can access or who maintains them. Visibility has to come before scale.
In practice:
- Define each agent's data access and permitted actions per task, not just per system.
- Design the escalation path. When the agent stops, decide what context reaches the human who takes over.
- Keep a register of agents, owners, and access rights before growth makes it impossible.
For the AI TestBed work at GPT-Lab, this gives governance a concrete purpose: helping partners test whether an agent supports their process within agreed limits, before those limits are tested by real customers. Testing builds the confidence employees need to use the assistance and shows the organization where it needs to improve.
2. Technology: from capable models to dependable systems
The technical discussions covered the full agent development lifecycle, from building and evaluating agents to running them in production. A large share of attention went to practical details that rarely make headlines: retrieval, tool use, sandboxing agent actions, and recovering from failure. Hybrid architectures, robotics, and physical AI widened the conversation to settings where a wrong action has consequences beyond a screen.
Recovery is part of the design. A workshop on durable execution made the reliability challenge tangible. Imagine an agent updating a business record that loses its connection before the confirmation arrives. Simply retrying might create a duplicate. The system must first establish what actually happened and only then continue. For the employee waiting on the result, this detail decides whether the agent can be trusted with real work.
Memory must be correctable. Remembering a customer's preferences saves people from explaining the same background again and again. But preferences change, and an instruction given months ago may no longer apply. Memory is only an asset when what the agent relies on can be inspected and revised.
Judge the path, not only the answer. A convincing final response can hide a failure along the way: a wrong tool call, a skipped check, a fact retrieved from the wrong source. Evaluation needs to examine the full trajectory an agent took, and evidence from real use should guide the next version. Development and evaluation can no longer be separate phases.
Beyond the screen. World models that connect language with visual and physical understanding, and robotics that brings this capability into factories and open environments, expand what AI can help accomplish. They also raise the stakes. Timing, predictability, and safe recovery matter directly when an agent moves something physical.
In practice:
- Make every agent action safe to repeat, or verifiable, before allowing automatic retries.
- Treat agent memory as data with an owner that can be reviewed and corrected.
- Log and evaluate complete agent trajectories, not only final outputs.
- Run agents in sandboxed environments before granting them access to production systems.
For GPT-Lab, this points to a clear research direction: understanding how an agent's earlier experience can improve its next task without carrying forward an earlier mistake.
3. Infrastructure: can the capability be sustained?
Sovereign AI was one of the dominant themes of the summit, and the discussion was strikingly physical. It ran from chips to models, through the security of supply chains, to the limits imposed by energy. Data centre design was discussed not only as an engineering challenge but also in terms of its relationship with the surrounding community.
Beneath these topics sat one question: who can sustain the capability being built? A service can look promising in a trial and still be too expensive or too fragile for its users to maintain.
Sovereignty means the ability to operate. In 2025, sovereignty appeared as an emerging concern alongside more efficient infrastructure. This year, the physical dependencies were impossible to miss. Compute must be available, but an organization also needs the skills to run its service and the freedom to respond when a supplier changes its terms. Ownership helps, but the ability to maintain and move a service is also a form of control.
Cost is decided in the design. Infrastructure questions reach down into the design of individual agents. An agent that keeps retrying a failing task consumes resources without making progress. Choosing an appropriately sized model and avoiding unnecessary calls make everyday use affordable. Operating cost should be understood before employees build routines around a service.
In practice:
- Know where your data goes and whether the workload could move without starting over.
- Estimate the running cost per completed task during the pilot, not after rollout.
- Build the in-house skills to operate the service, not only to purchase it.
For Finland and Europe, the opportunity is to connect shared computing infrastructure with practical support. A smaller company with a worthwhile problem should have a clear route to testing an idea. Access becomes far more valuable when the company also gets help deciding whether the application is worth sustaining.
4. Industry practice: value across the whole task
Industry sessions kept returning to integration rather than adoption, and to the human side of scaling AI. Most organizations already use AI somewhere. The difficulty is fitting it into processes that were never designed for agents and turning pilots into measurable results. Customer experience discussions linked automation to the quality of service people actually receive, while workshops focused on escaping the proof-of-concept stage.
The 2025 reflection described enterprises moving from experimenting with AI to standardizing it. That ambition remains, but this year the work required to get there was much more visible. An application can perform well in isolation and still fit poorly into the process employees actually use.
Measure the whole task. An agent may produce a report in minutes, yet if every claim needs checking, the saving disappears. If the system instead helps an employee reach a sound answer sooner, it frees time for the part of the request that needs human judgment. The right measure is the complete task, including review.
Speed is not service. Faster handling matters when it resolves the customer's problem. A quick response that misreads the situation creates more work for everyone. The people delivering the service understand where assistance would help, and they need a role in shaping it.
Protect the path to expertise. Experienced employees can tell when an answer sounds plausible but does not fit the case. That judgment was built through years of routine work, the same work AI now absorbs. Several discussions raised the risk that today's efficiency gains erode the expertise organizations will rely on tomorrow. Organizations need to preserve learning opportunities for newer staff deliberately, and education needs to prepare people to question the behaviour of systems they can now build with ease.
In practice:
- Define success as the time to a correct, accepted result, including review effort.
- Involve frontline staff in deciding where AI assists and where it does not.
- Agree in advance what evidence would justify stopping a pilot, not only scaling it.
For GPT-Lab, the opportunity is to bring research into this everyday setting. A prototype gives a partner something concrete to try. Evaluation helps them decide whether to proceed, and often reveals a research question that was hard to see in isolation. That is how collaboration produces value on both sides.
Looking toward 2027: life after the first deployment
Attention in 2027 is likely to shift to what happens after the first deployment. The real test is whether AI still helps six months later, once the novelty has gone and it has become part of ordinary work. The summit offered a clear direction for different groups.
SMEs: Start with one problem that employees can describe clearly. A focused trial makes it easier to judge the benefit before taking on a larger commitment. That judgment should include the effort needed to check results and the cost of keeping the service running. Working with a university or a testbed makes the first step more manageable.
Large companies: Coordination becomes essential. Teams may build useful agents while the organization loses track of what they access or who supports them. Shared evaluation practices help teams learn from one another, and clear ownership makes it easier to extend a successful use case.
Research institutes: Follow systems beyond the short demonstration. Working with partners to observe what happens over time, including cases where the benefit fades, improves engineering and gives industry better evidence for investment. It also gives students the chance to learn from systems that people actually use.
National level: The ambition for sovereign AI needs to connect with the capacity of organizations to benefit from it. Compute access needs to be matched with skills and a sustainable plan for operation, and energy planning belongs in the same conversation. For Finland, the opportunity is to make the link between research capability and industrial needs easier to act on.
Five questions to ask before deploying an agent
- What exactly is the agent allowed to do, and on whose behalf?
- What happens when it fails halfway through a task?
- Who owns it, and who reviews what it remembers?
- What does one completed task cost to run, including human checking?
- How will we know, six months from now, that it still helps?
Carrying the momentum home
The Finnish group returned from Amsterdam with different notes, contacts, and priorities. The next step is to bring those perspectives together around concrete partner problems. Through GPT-Lab, the aim is to connect research with those problems and use prototypes to discover what deserves further investment.
In 2025, the summit showed that AI had taken a practical turn. In 2026, it showed what practicality demands: governance built into the workflow, engineering for failure, infrastructure that can be sustained, and organizations willing to change how work is done. AI has grown up. The organizations that benefit in 2027 will be those whose practices grow up with it. And the clearest sign of success will be simple: a partner who can explain what has become easier because of the work done together.
Further reading
